Testing in AIDLC: From Acceptance Criteria to Release
In AIDLC the acceptance criteria drive the tests, and the tests drive the code. This page puts the whole strategy in one place: which test is written in which phase and by whom, how to write criteria an agent can turn into the right tests, the rules that keep AI-generated tests honest, and what happens when a gap turns up late.
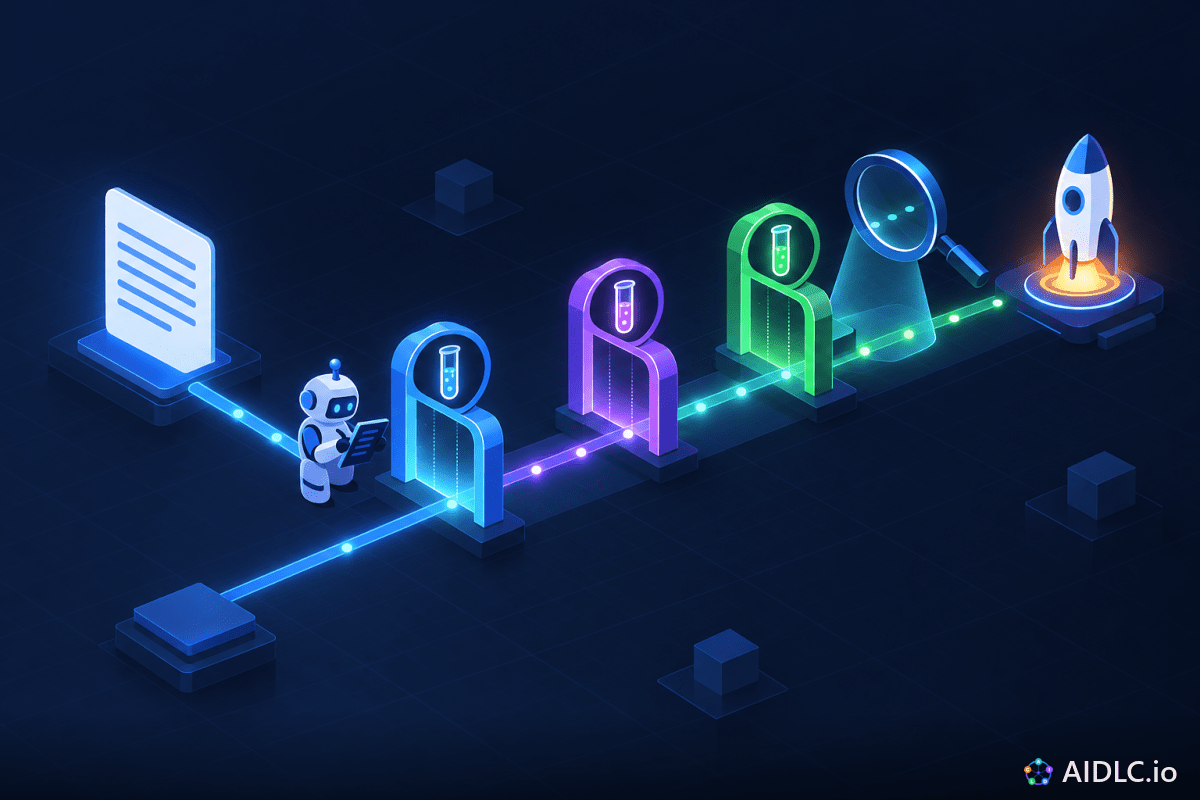
The Criteria Drive the Tests
The chain runs in one direction. Analyze writes acceptance criteria as Given/When/Then. Ideate fixes the contracts at every module boundary. Develop turns each criterion into a test, at the level the criterion needs, before any implementation exists, and builds until the tests pass. Launch verifies the integrated release against that suite rather than writing a new one.
None of this is new in spirit. It is the lineage of test-driven development, acceptance test-driven development (ATDD) and behavior-driven development (BDD), whose Given/When/Then format the Analyze brief uses. What AI changes is the economics: an agent can generate the tests from well-written criteria in minutes, so writing them first is no longer the expensive option. It also changes the risk: an agent can just as quickly generate tests that look thorough and assert nothing, which is why the rules further down matter.
Who Writes Which Test, and When
Almost every test is written in Develop. Launch runs them, and writes one only when it finds a gap. The table is the reference; the sections after it explain the choices.
| Test or check | What it proves | Specified in | Written in | Runs |
|---|---|---|---|---|
| Acceptance criteria | What done means, as observable behavior | Analyze | Not a test yet: the source of every test | - |
| Unit tests | A piece of logic does what the criterion says | Analyze | Develop, before the code | Every commit |
| Contract tests | Each side of an interface honors the agreed contract | Ideate (the contract) | Develop, before the code | Every pull request |
| Integration tests | Modules and external systems work together across a boundary | Ideate (the boundaries) | Develop, by the ticket that touches the boundary | Every pull request |
| End-to-end journey tests | A user can complete a journey through the whole system | Ideate (the journeys) | Develop, by the ticket that completes the journey | Pull request and release candidate |
| Mutation gate | The tests would notice if critical logic changed | QA lead sets thresholds | Develop's gate, per pull request | Pull requests touching critical modules |
| Evals | A prompt, model or retrieval setup behaves acceptably | Analyze (blocking cases) | Develop, before the prompt or model change | Every prompt or model change |
| Characterization tests | What legacy code does today, before anyone changes it | - | Develop, before the first change | Every pull request |
| Full suite on the integrated build | Everything still works together once merged | - | Not written: Launch runs it | Release candidate |
| Gap tests | Something the suite missed | - | Launch, only when a gap is found | From then on, every pull request |
| Smoke tests and health checks | The release works in production | Launch (release plan) | Launch | After each deploy |
| Production checks and new eval cases | Behavior holds in the field | Curate | Curate, after each incident | Continuously |
Writing Criteria an Agent Can Test
An agent writes exactly the tests the criteria imply, and nothing the criteria leave unsaid. Most late gaps trace back to a criterion that was vague, bundled two behaviors, or never named the boundary it crossed.
Six rules
- One behavior per criterion. "And" in a Then clause usually means two criteria.
- An observable outcome. Something a test can assert, not "works correctly" or "is fast".
- The data state in Given. Which records exist, in what condition, for which user.
- The negative cases. What must never happen is a criterion too, and often the most important one.
- An ID. So the spec, the tests and the pull request can each point back to it.
- The boundary it crosses. Naming the service or external system tells Develop to write an integration or contract test, not only a unit test.
A criterion, written well
AC-2  Tenant isolation on export        (crosses: billing-service -> export-worker)
Given two accounts, A and B, on the same tenant, each with paid invoices
When  the owner of account A requests a CSV export
Then  the file contains only account A's invoices

AC-3  Export of an empty account
Given an account with no invoices
When  the owner requests a CSV export
Then  the file contains the header row and no data rows
AC-2 names a boundary, so Develop writes an integration test across it as well as unit tests for the filter. AC-3 is the edge case a demo never shows.
| Vague criterion | What goes wrong | Testable rewrite |
|---|---|---|
| "Export should be fast." | No outcome to assert; the agent writes no test, or an arbitrary one | Given the largest account named in the brief, When the owner requests an export, Then the file is ready within the time limit the brief sets. |
| "Users can export and email invoices." | Two behaviors; one gets a test, the other gets assumed | Split into two criteria with their own IDs, one for the export and one for the email. |
| "Handle errors gracefully." | The agent invents its own idea of graceful | Given the export worker is unavailable, When the owner requests an export, Then they see a retry message and no partial file is created. |
| "Only show the user's own data." | No data state and no boundary, so it gets a unit test and nothing more | The AC-2 form above: two accounts in Given, the boundary named, an exact Then. |
A prompt that drafts and checks criteria like these is in the Prompt Library, and the criteria field lives in the ticket contract template.
Choosing the Test Level
The level follows from the criterion and the ticket contract, so it is decided before the code, not discovered after it.
Unit
The criterion is about a calculation, a rule or a transformation inside one module.
Contract or integration
The criterion crosses a module boundary or an external system the ticket contract names.
End to end
The ticket completes a user journey Ideate listed. That ticket owns the journey's test.
Eval
The behavior comes from a prompt, a model or retrieval rather than from code.
Many criteria need more than one level: AC-2 above gets unit tests for the filter and an integration test across the boundary. A criterion that seems to need no test at any level is the one to send back to Analyze.
Rules for AI-Generated Tests
Agents are good at producing tests that exercise code and weak at asserting outcomes. These rules close that gap, and each one can be enforced by a hook or a CI check rather than by hope. See Implementation Examples for the scripts.
Generate from the criteria, not the code
A test generated from the implementation confirms whatever the code already does, bugs included. A test generated from the criterion checks what the code should do.
See it fail first
A new test that passes before the implementation exists is testing nothing. Make the gate check that new tests fail without the change.
Never edit a test to get green
An agent may add tests. It may not weaken, skip or delete an existing one to make a build pass. A changed test needs a stated reason and a person.
Gate on mutation, not coverage
Coverage shows which lines ran. A mutation score on critical modules shows whether the tests would notice a real change. See tests first, mutation scored.
Synthetic test data only
Agents build fixtures from the data state in the criteria, never from copies of production records. Personal data in a fixture is a data incident waiting in the repo.
Quarantine flaky tests openly
A flaky test goes to quarantine with a ticket and an owner. An agent that silently retries until green teaches the whole team to distrust the suite.
When Launch Finds a Gap
Launch runs the full suite on the integrated build and looks for what it misses, with an independent critic and a mutation re-check. A gap becomes a test, and what happens next depends on that test.
The gap test fails
It found a defect. The failing test goes back to Develop as the feedback artifact, and the work loops until it passes. Launch does not fix the code.
The gap test passes
The code was right and the suite was thin. The test is kept, and the Develop gate that should have required it is tightened. No rework.
Either way, count it. Gaps found in Launch are a metric, not a workflow: a rising number means the criteria or Develop's gates need fixing upstream, not that Launch needs more capacity. The full set of backward moves is on How the Phases Connect.
Frequently Asked Questions
In Develop, before the code. Each acceptance criterion from Analyze becomes a unit, integration, contract or end-to-end test, at the level the criterion needs, and the agent implements until those tests pass. Launch runs the full suite against the integrated release and writes a new test only when it finds a gap.
It builds on them. AIDLC uses the Given/When/Then acceptance criteria of behavior-driven development and the tests-before-code order of acceptance test-driven development. What it adds is the agent: well-written criteria let a coding agent generate the tests before it writes the implementation, with gates that stop it from weakening those tests later.
Yes, under rules. Agents should generate tests from the acceptance criteria rather than from the code, show that each new test fails before the implementation exists, never edit or skip an existing test to make a build pass, and be gated on a mutation score for critical modules rather than on coverage. A person reviews the tests like any other code.
Start With the Criteria
Better tests start in Analyze. Write the next brief's criteria with the six rules above, then watch how little Launch has left to find.